Tokens and tokenization: how language models read text
When you type a sentence into a language model, the model does not usually process it as a list of ordinary words.
First, the text is broken into smaller units called tokens. That process is called tokenization.
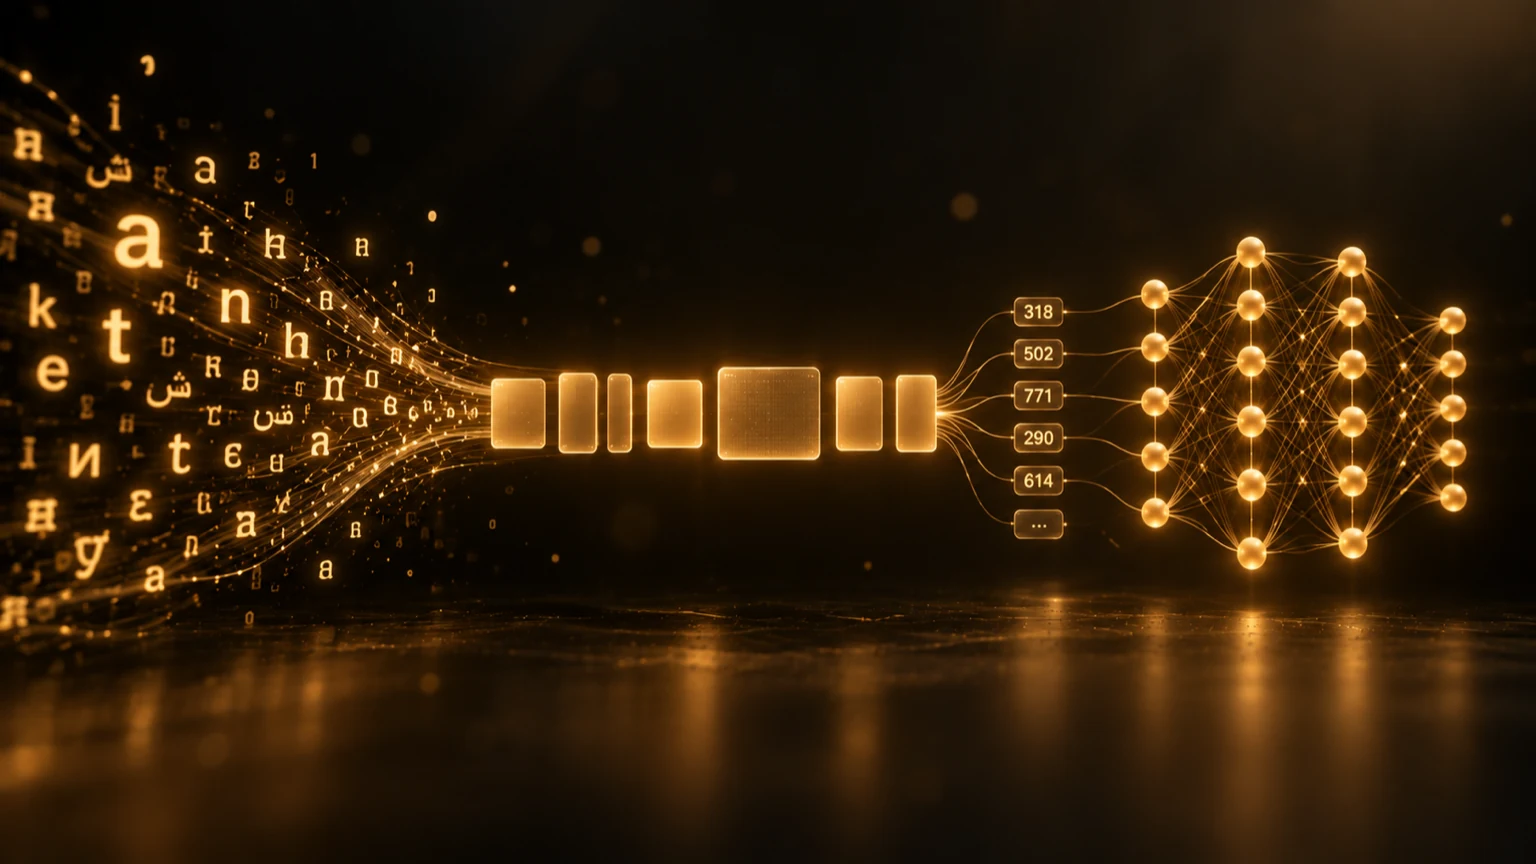
In simplified form, text reaches the model like this:
- You write text.
- The tokenizer splits it into tokens.
- Each token is replaced with its number, the token ID.
- The language model processes those numbers.
Tokens are one of the basic building blocks of modern language models. They affect how text is represented, how much context a model can process, how quickly it runs, and often how usage is measured.
What is a token?
A token is a unit of text that a model works with. A token can be:
- a whole word;
- part of a word;
- punctuation;
- a number;
- a space combined with nearby characters;
- or, in some tokenizers, even a single character or byte sequence.
So a token is not the same thing as a word.
Depending on the tokenizer, a common word may be stored as one token, while a longer or less common word may be split into several pieces. One tokenizer might split tokenization into token and ization; another may split the same word differently.
The important point is that the tokenizer decides the boundaries, not the spaces between words.
What is tokenization?
Tokenization is the process of converting raw text into the token units used by a model.
A tokenizer usually has a vocabulary: a fixed collection of token pieces it knows how to represent. Each token in that vocabulary has a numerical identifier called a token ID.
For example, the sentence “AI is useful.” might become four tokens:
| Token | Token ID |
|---|---|
| “AI” | 4210 |
| “is” | 374 |
| “useful” | 5505 |
| “.” | 13 |
The split and the numbers are only an illustration; real tokens and IDs depend on the tokenizer. Here every word happens to be a single token, while a rarer word would be split into pieces.
The model itself works with numbers. Token IDs are therefore used to look up learned vectors, often called embeddings, that the neural network can process.
When a language model generates text, the direction is reversed: it predicts token IDs, and the tokenizer decodes them back into readable text.
Why not just use words?
Using one token for every possible word sounds simple, but it creates several problems.
Languages contain huge numbers of words, names, technical terms, spelling variants, and newly created expressions.
If every complete word needed its own token:
- the vocabulary could become extremely large;
- rare words would be difficult to represent;
- new words might be completely unknown;
- languages with many word forms would need many separate entries.
Using only individual characters solves the unknown-word problem, but then ordinary text becomes a very long sequence.
Modern language models therefore often use a compromise: subword tokenization.
A frequent word or word piece can stay together, while a rare word can be split into smaller reusable pieces. That gives the model a manageable vocabulary while still allowing it to represent almost any text.
Common tokenization methods
There are several ways to build a tokenizer. Three names appear frequently in modern NLP:
- BPE (Byte Pair Encoding): starts from single characters or bytes and repeatedly merges the most frequent adjacent pair into a new token;
- WordPiece: builds a vocabulary of useful word pieces and is known from models such as BERT;
- Unigram: starts with a large set of candidate pieces and keeps the ones a probabilistic model finds most useful.
The exact algorithm matters less to a general reader than the main idea:
A tokenizer learns or defines a useful set of text pieces and converts text into those pieces consistently.
Different model families can therefore use different tokenizers even when they process the same language.
Why can the same sentence have different token counts?
Because tokenization depends on the tokenizer.
Two models can have different vocabularies. One tokenizer may already contain a common word as a single token, while another needs two or three pieces for it.
So the same sentence might come to 8 tokens with tokenizer A and 11 tokens with tokenizer B, even though the visible text is identical.
This is why word count and token count are not interchangeable.
For common English text, some tokenizers average roughly a few characters per token, but that is only a rough estimate. It should not be treated as a universal rule across languages, writing systems, or models.
Why does language matter?
Tokenizer quality can differ significantly between languages.
A tokenizer built from data dominated by one language may represent that language very efficiently but split words from another language into many smaller pieces.
This matters for languages with rich word formation, different alphabets, special punctuation, or less representation in the tokenizer’s training data.
Uzbek is a useful example. A single root can take many suffixes, and Uzbek text may be written in Latin or Cyrillic script and use several apostrophe-like characters. A tokenizer that represents common Uzbek patterns well can process the language more efficiently than one whose vocabulary barely contains them.
This is not just a theoretical issue. When NeuronAI built MustaqiLLM, the tokenizer was part of the model design: the published model uses a 48,000-token BPE tokenizer and was specifically adapted for Uzbek.
That is a good reminder that the tokenizer is not an invisible formatting detail. For multilingual and local-language AI, it is an important part of model design.
Tokens and the context window
Language models can only process a limited amount of information at once.
This limit is commonly called the context window, and it is usually measured in tokens rather than words.
Suppose a model supports a context window of 128,000 tokens. That budget may need to hold the user’s prompt, relevant conversation history, system instructions, documents, and other text the model must consider.
A document with fewer words is not always guaranteed to use fewer tokens than another document, especially across different languages or tokenizers.
Efficient tokenization therefore helps a model fit more useful text into the same context budget.
Tokens, speed, and cost
Tokens also matter in day-to-day use.
For many hosted AI services, usage is measured partly by the number of input tokens and output tokens.
More tokens generally mean that the model has more units to process. That can affect:
- inference time;
- memory use;
- compute requirements;
- API cost;
- how much information fits into the context window.
This does not mean that the shortest possible prompt is always best. Clear context can improve results.
The practical goal is to avoid unnecessary text while preserving the information the model actually needs.
How do tokens work in an LLM response?
Large language models generate text one token at a time. A simplified generation loop looks like this:
- The model reads the prompt tokens.
- It calculates a probability for each possible next token.
- One token is selected.
- That token is added to the sequence.
- The loop repeats until the answer is complete: the model predicts the next token from the longer sequence.
That is what our article on LLMs means when it says language models predict the next token.
A complete answer may take hundreds or thousands of such steps. The final text looks continuous to us, but internally it was built token by token.
Are tokens always visible text?
No.
Some systems use special tokens that are not meant to appear as ordinary text. They can mark things such as:
- the beginning or end of a sequence;
- boundaries between messages;
- different roles in a conversation;
- padding, filler tokens that bring sequences to the same length;
- other control information.
The exact special tokens depend on the model and tokenizer.
So the number of tokens used by a system can sometimes include more than the visible words in a prompt.
Is the tokenizer part of the model?
It is best to think of the tokenizer as a tightly connected part of the model pipeline.
The tokenizer defines the vocabulary and assigns token IDs. During training, the model learns representations for those IDs.
Because of that connection, replacing the tokenizer of an already trained model is not as simple as changing a text-processing setting. If the vocabulary changes, the link between token IDs and the model’s learned embeddings breaks.
That is why the tokenizer is usually chosen before or during model development, not casually replaced after training.
Does tokenization understand meaning?
No.
The tokenizer’s job is to split and encode text. It does not need to understand a sentence the way a language model attempts to model relationships within it.
For example, a tokenizer may split a technical word into several pieces simply because those pieces are efficient for its vocabulary. The language model then learns how those tokens relate to one another through training.
So the work is divided in two:
- Tokenizer: text → token pieces → token IDs.
- Model: token representations → learned relationships → prediction.
Tokenization prepares the language for the model. The model does the pattern learning.
The easiest way to remember it
If you remember only two ideas, use these:
A token is a piece of text a model works with.
Tokenization is the process of splitting text into those pieces and converting them into IDs.
In one line: text → tokenizer → tokens → numbers → model.
This small preprocessing step has surprisingly large consequences. It affects how efficiently a model handles different languages, how much text fits into its context window, how usage is counted, and how language reaches the neural network in the first place.
Before an LLM can predict the next token, it first needs a tokenizer to decide what a token is.